Fudan University · FudanNLP
Hey! I'm Zhaoye.
Foundation models. Embodied intelligence.
Human–AI interaction.
About me
I am a PhD student at Fudan University, advised by Prof. Xipeng Qiu, and a member of FudanNLP. I received my bachelor’s degree from Hangzhou Dianzi University.
My research centers on foundation models and intelligent agents, with three main interests:
- LLM Pre-training & Multimodal Integration: Learning general-purpose representations and integrating knowledge across language, vision, and audio.
- Embodied Intelligence: World modeling, grounded reasoning, and learning to plan and act in physical environments.
- Human–AI Interaction: Speech and audio understanding and generation for natural, real-time interaction.
My work has appeared at NeurIPS, ICML, ICLR, ACL, and CVPR. I also contribute to the open-source InternLM and MOSS model families.
I am a member of vidar-team and the dedicated photographer of @blueblueO908.
News
- I will curate the Real-Time AI Infra session at iRTE 2026 in Beijing on October 24, 14:00–17:00! We will explore low-latency, high-concurrency and streaming inference for multimodal AI.
- We announce the release of EasyWAM, a unified and efficient framework for training, fine-tuning and evaluating World Action Models!
- The team I mentored won 1st place in Track 1 and 2nd place in Track 2 of the NVVSpeech Challenge at ISCSLP 2026, on understanding and generating speech with non-verbal vocalizations!
- The team I mentored won 1st place in both tracks of the SmartGlasses Challenge 2026, covering dyadic dialogue and multi-party meeting understanding!
- Teams I mentored won 1st place in both tasks of the 2nd MLC-SLM Challenge: multilingual speech diarization and recognition, and conversational speech understanding!
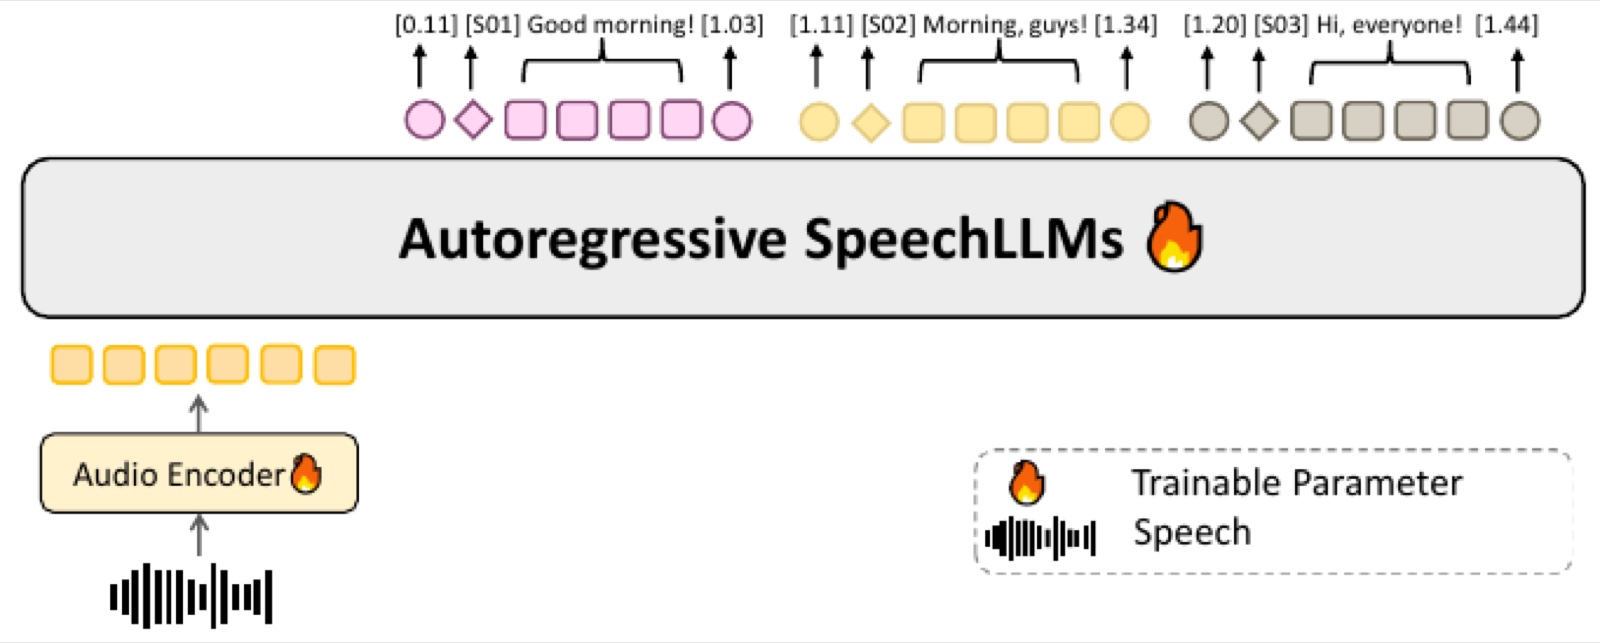
- We released MOSS-Transcribe-Diarize 0.9B, a lightweight model for transcription, speaker diarization and timestamps, with 691k total downloads on Hugging Face as of October 2026!
- We introduce HiMe, a hierarchical memory framework for long-horizon robot control!
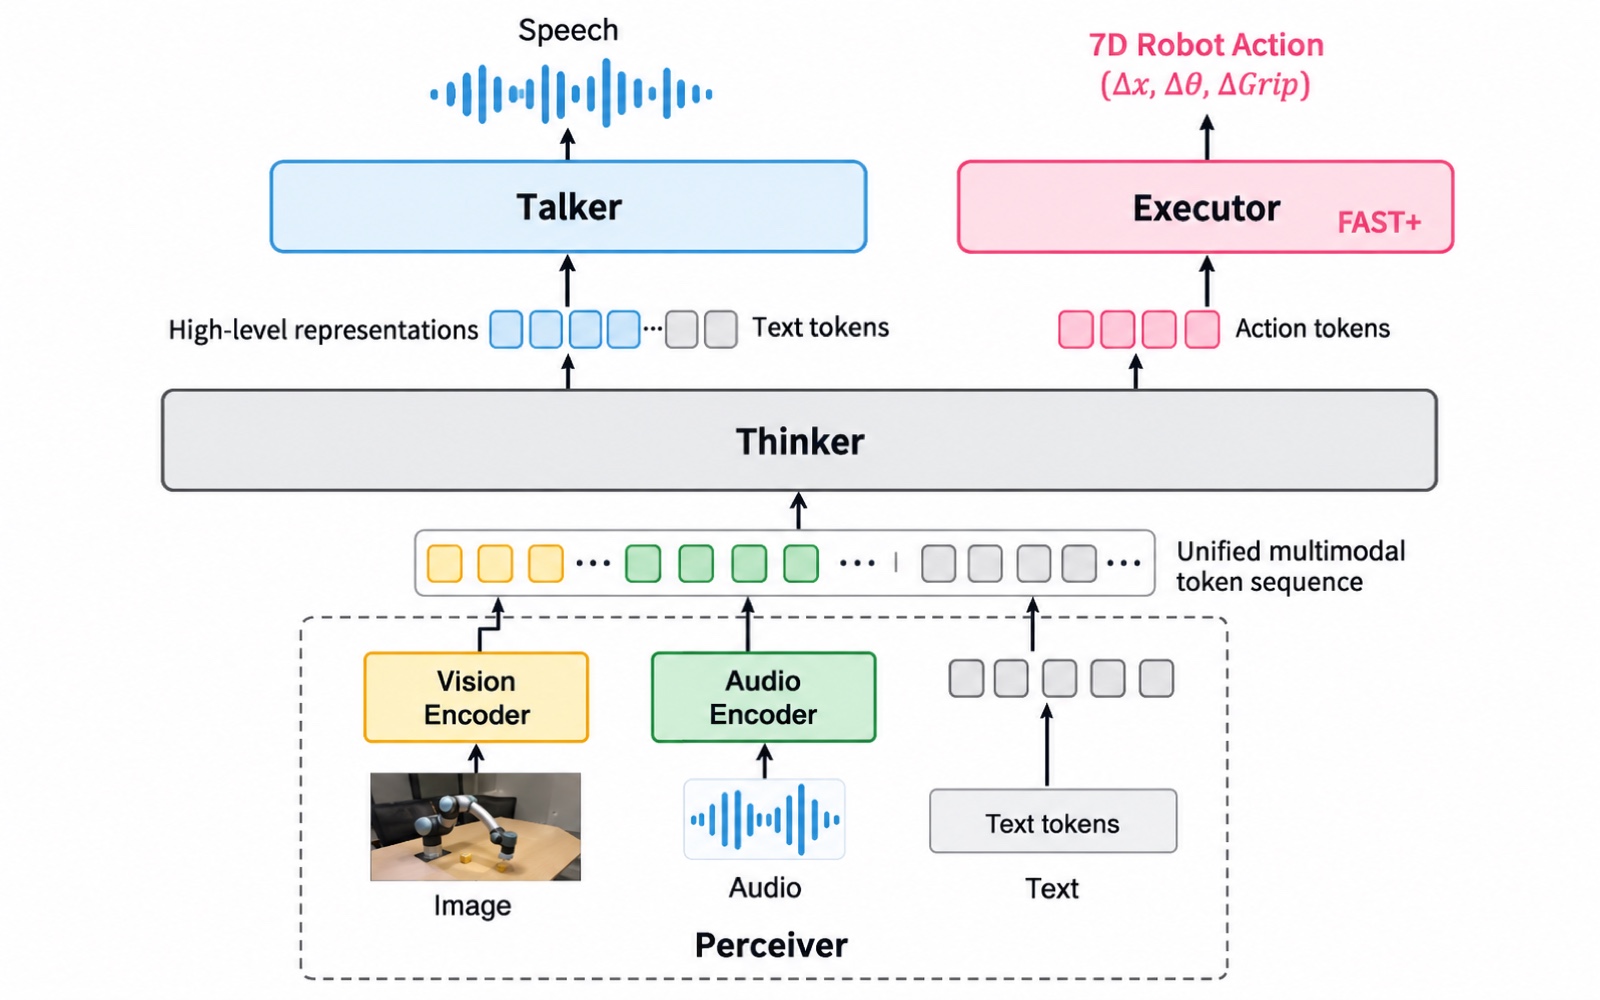
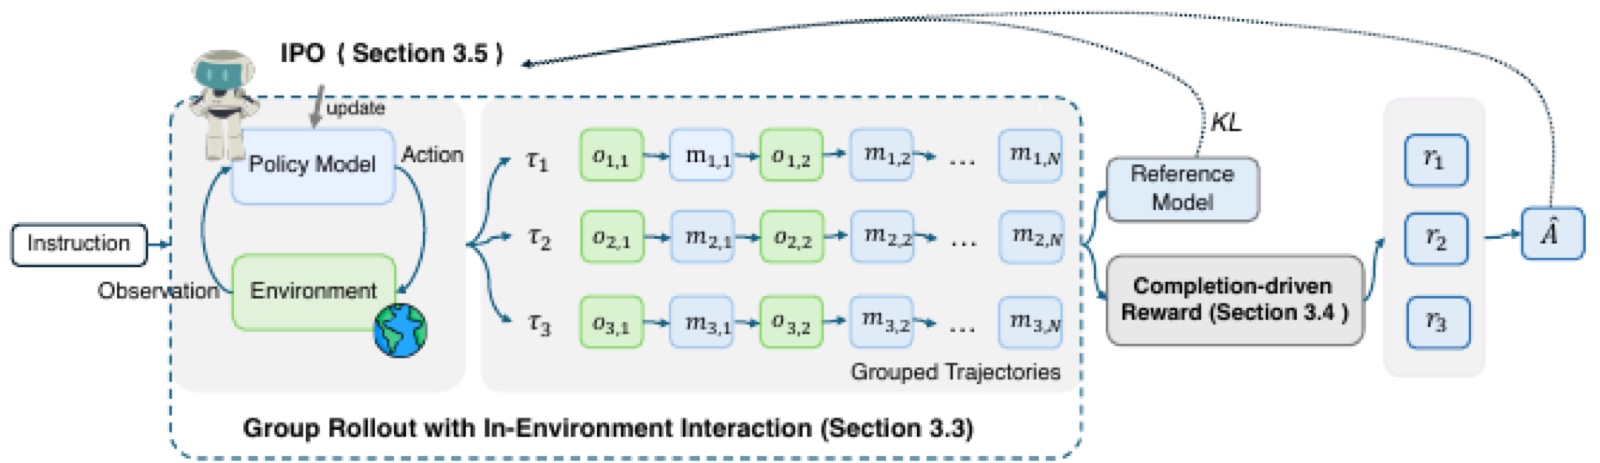
- We introduce OmniAct, an omnimodal embodied agent that coordinates robot skills and digital tools for sustained physical autonomy!
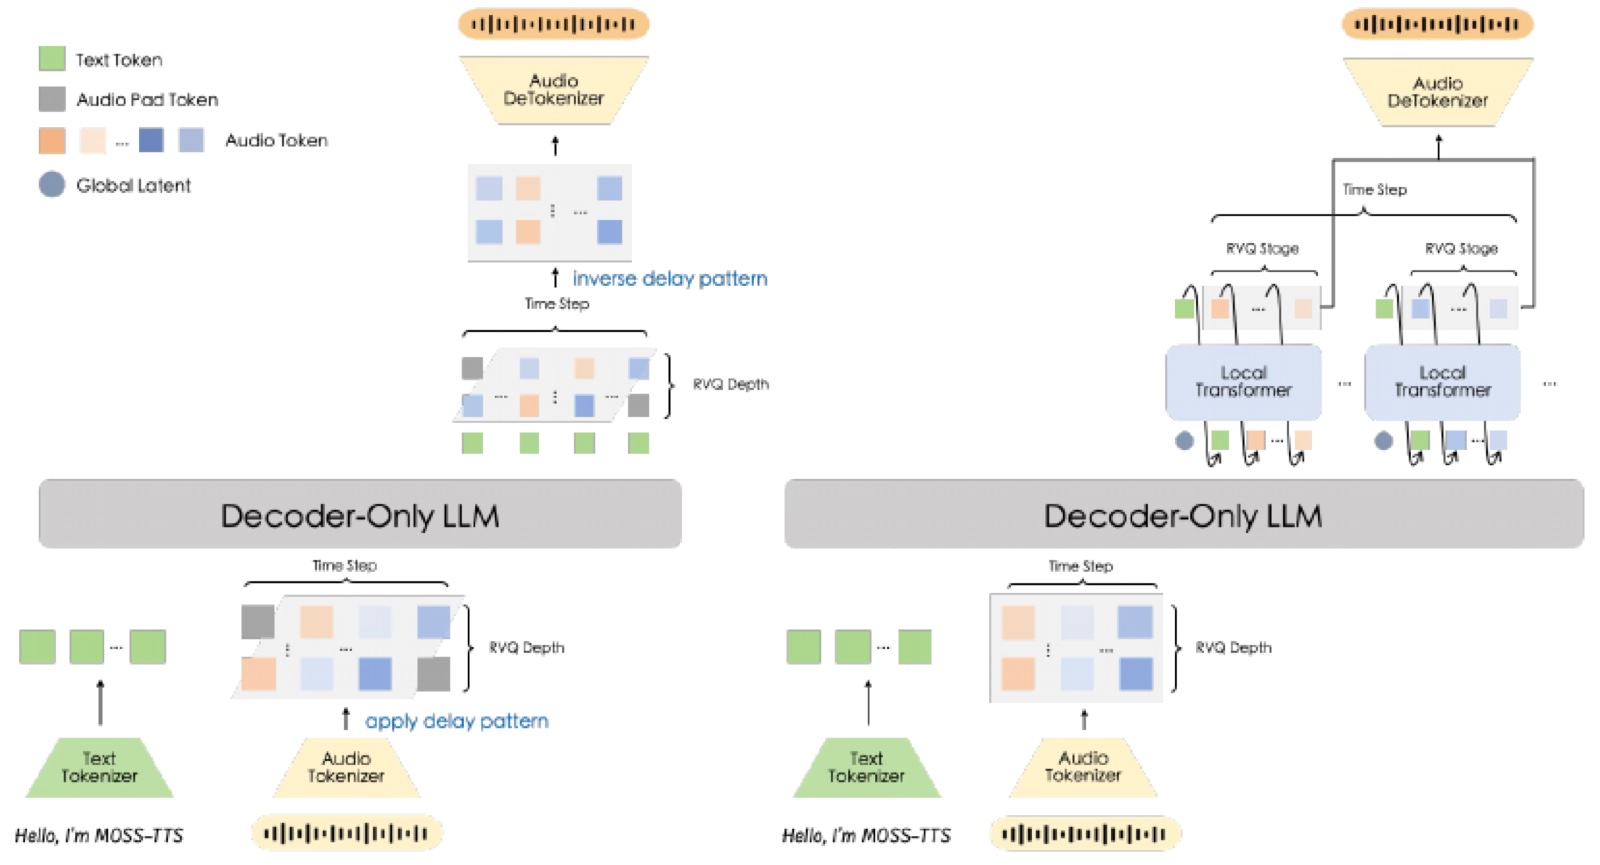
- We released MOSS-TTS-Local-Transformer v1.5, with 48 kHz stereo output, multilingual synthesis and more stable voice cloning! It has reached 393k total downloads on Hugging Face as of October 2026.
- One paper accepted to ICML 2026: Scaling Transformers for End-to-End Discrete Audio Tokenization!
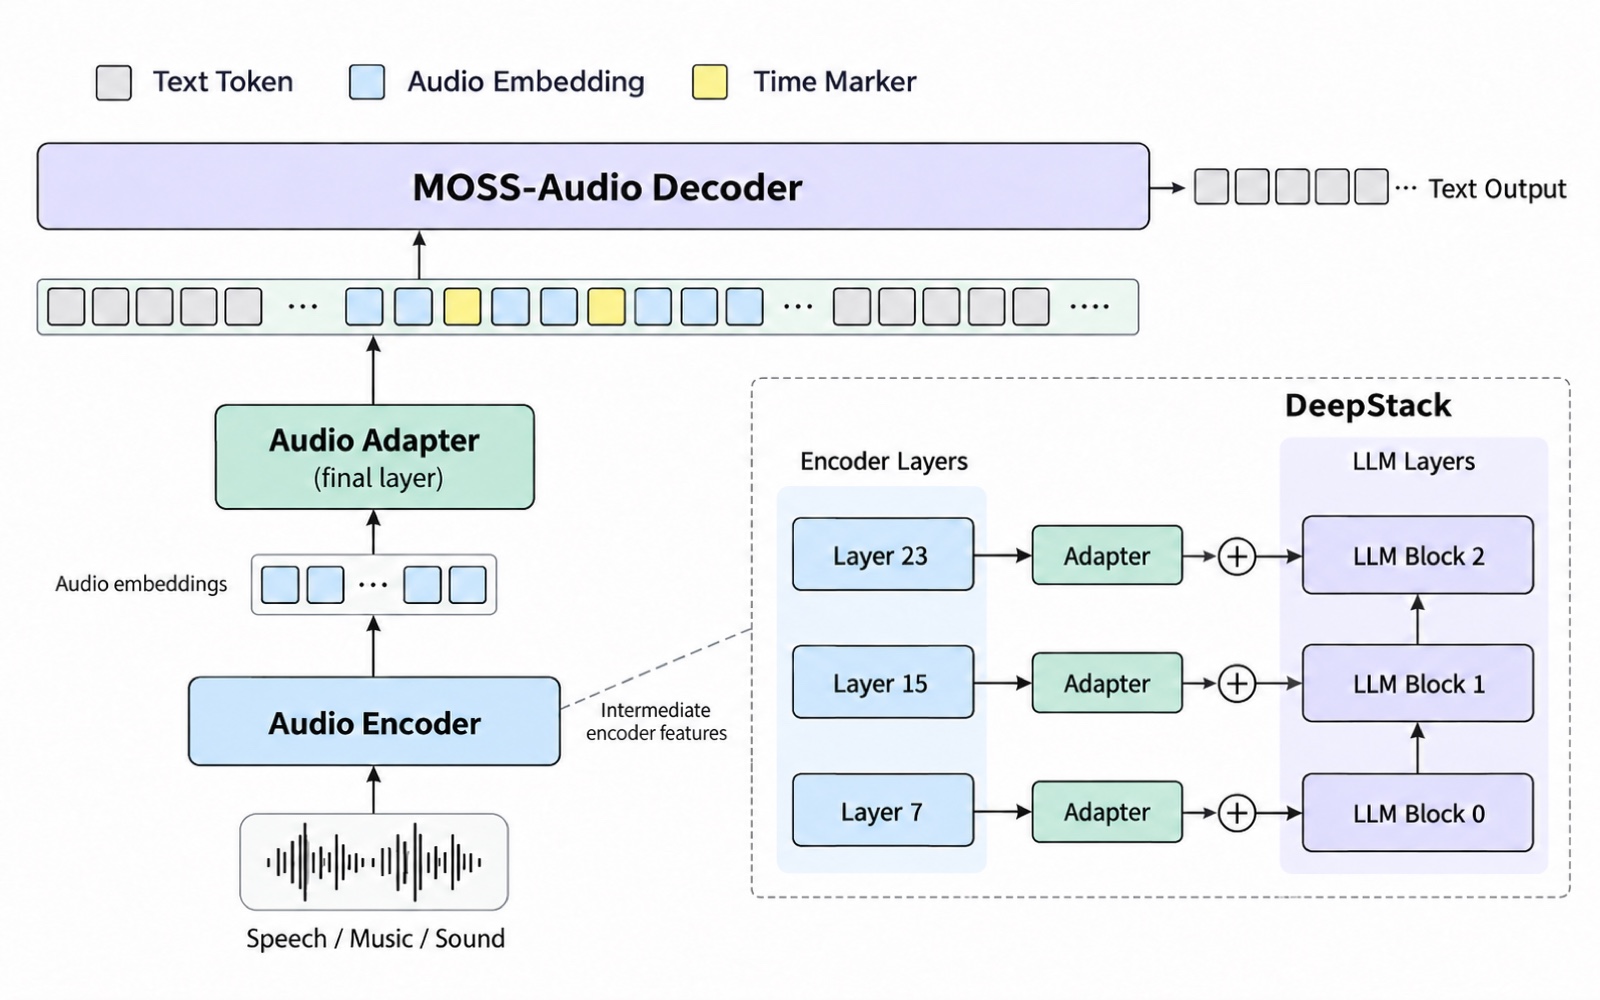
- We released MOSS-Audio, our open-source model family for speech, sound and music understanding, with time-aware captioning and audio-grounded reasoning! Its four 4B/8B Instruct and Thinking checkpoints have reached approximately 576k total downloads on Hugging Face as of October 2026. Technical report (June 2026).
- Two papers accepted to ACL 2026: XY-Tokenizer (Main) and WESR (Findings)!
- We introduce our MOSS-TTS family: MOSS-TTS for multilingual, controllable speech synthesis and voice cloning; MOSS-TTSD for expressive, long-form multilingual dialogue with consistent speaker voices; and MOSS-VoiceGenerator for voice design from text descriptions! Total Hugging Face downloads as of October 2026: MOSS-TTS (base) 1.56M, TTSD v0.5/v1.0 combined approximately 177k, and VoiceGenerator 154k.
- One paper accepted to CVPR 2026: LIBERO-Plus!
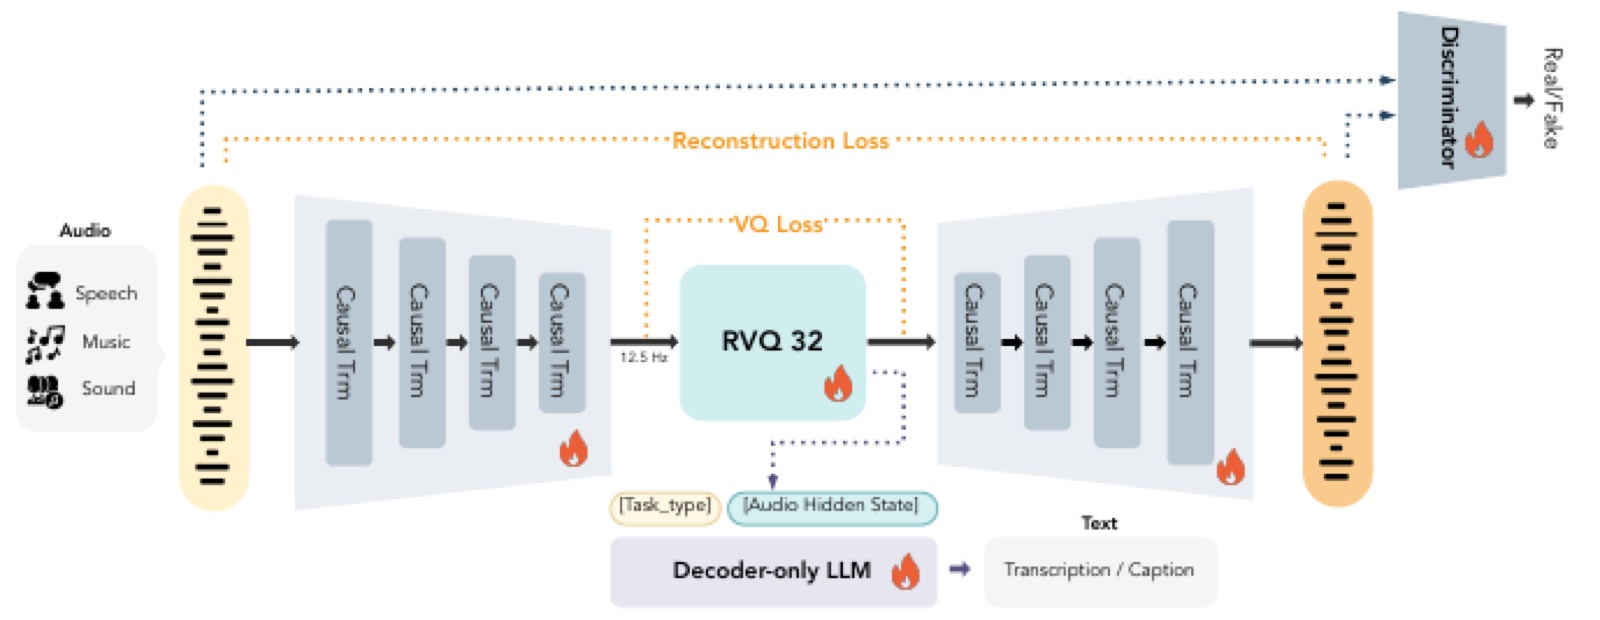
- We introduce MOSS-Audio-Tokenizer, achieving state-of-the-art audio reconstruction across speech, sound and music with a fully end-to-end causal Transformer architecture! The base checkpoint has reached 1.1M total downloads on Hugging Face as of October 2026.
- We introduce MOVA, an open-source model for jointly generating synchronized video and audio from image and text inputs! The MOVA-360p checkpoint has reached 734k total downloads on Hugging Face as of October 2026.
- Two papers accepted to ICLR 2026: MOSS-Speech and RoboOmni!
- We introduce MOSS Transcribe Diarize, a unified end-to-end model for transcription, speaker diarization and timestamps!
- Our paper on World-aware Planning was accepted to NeurIPS 2025! It strengthens vision-language planning through environment-grounded instruction enhancement and curriculum learning.
- We released MOSS-TTSD v0.5, an open-source model for expressive two-speaker dialogue in Chinese and English, with voice cloning and long-form generation!
- VLABench was accepted to ICCV 2025! The benchmark evaluates language-conditioned robot manipulation through implicit instructions, world knowledge and long-horizon reasoning.
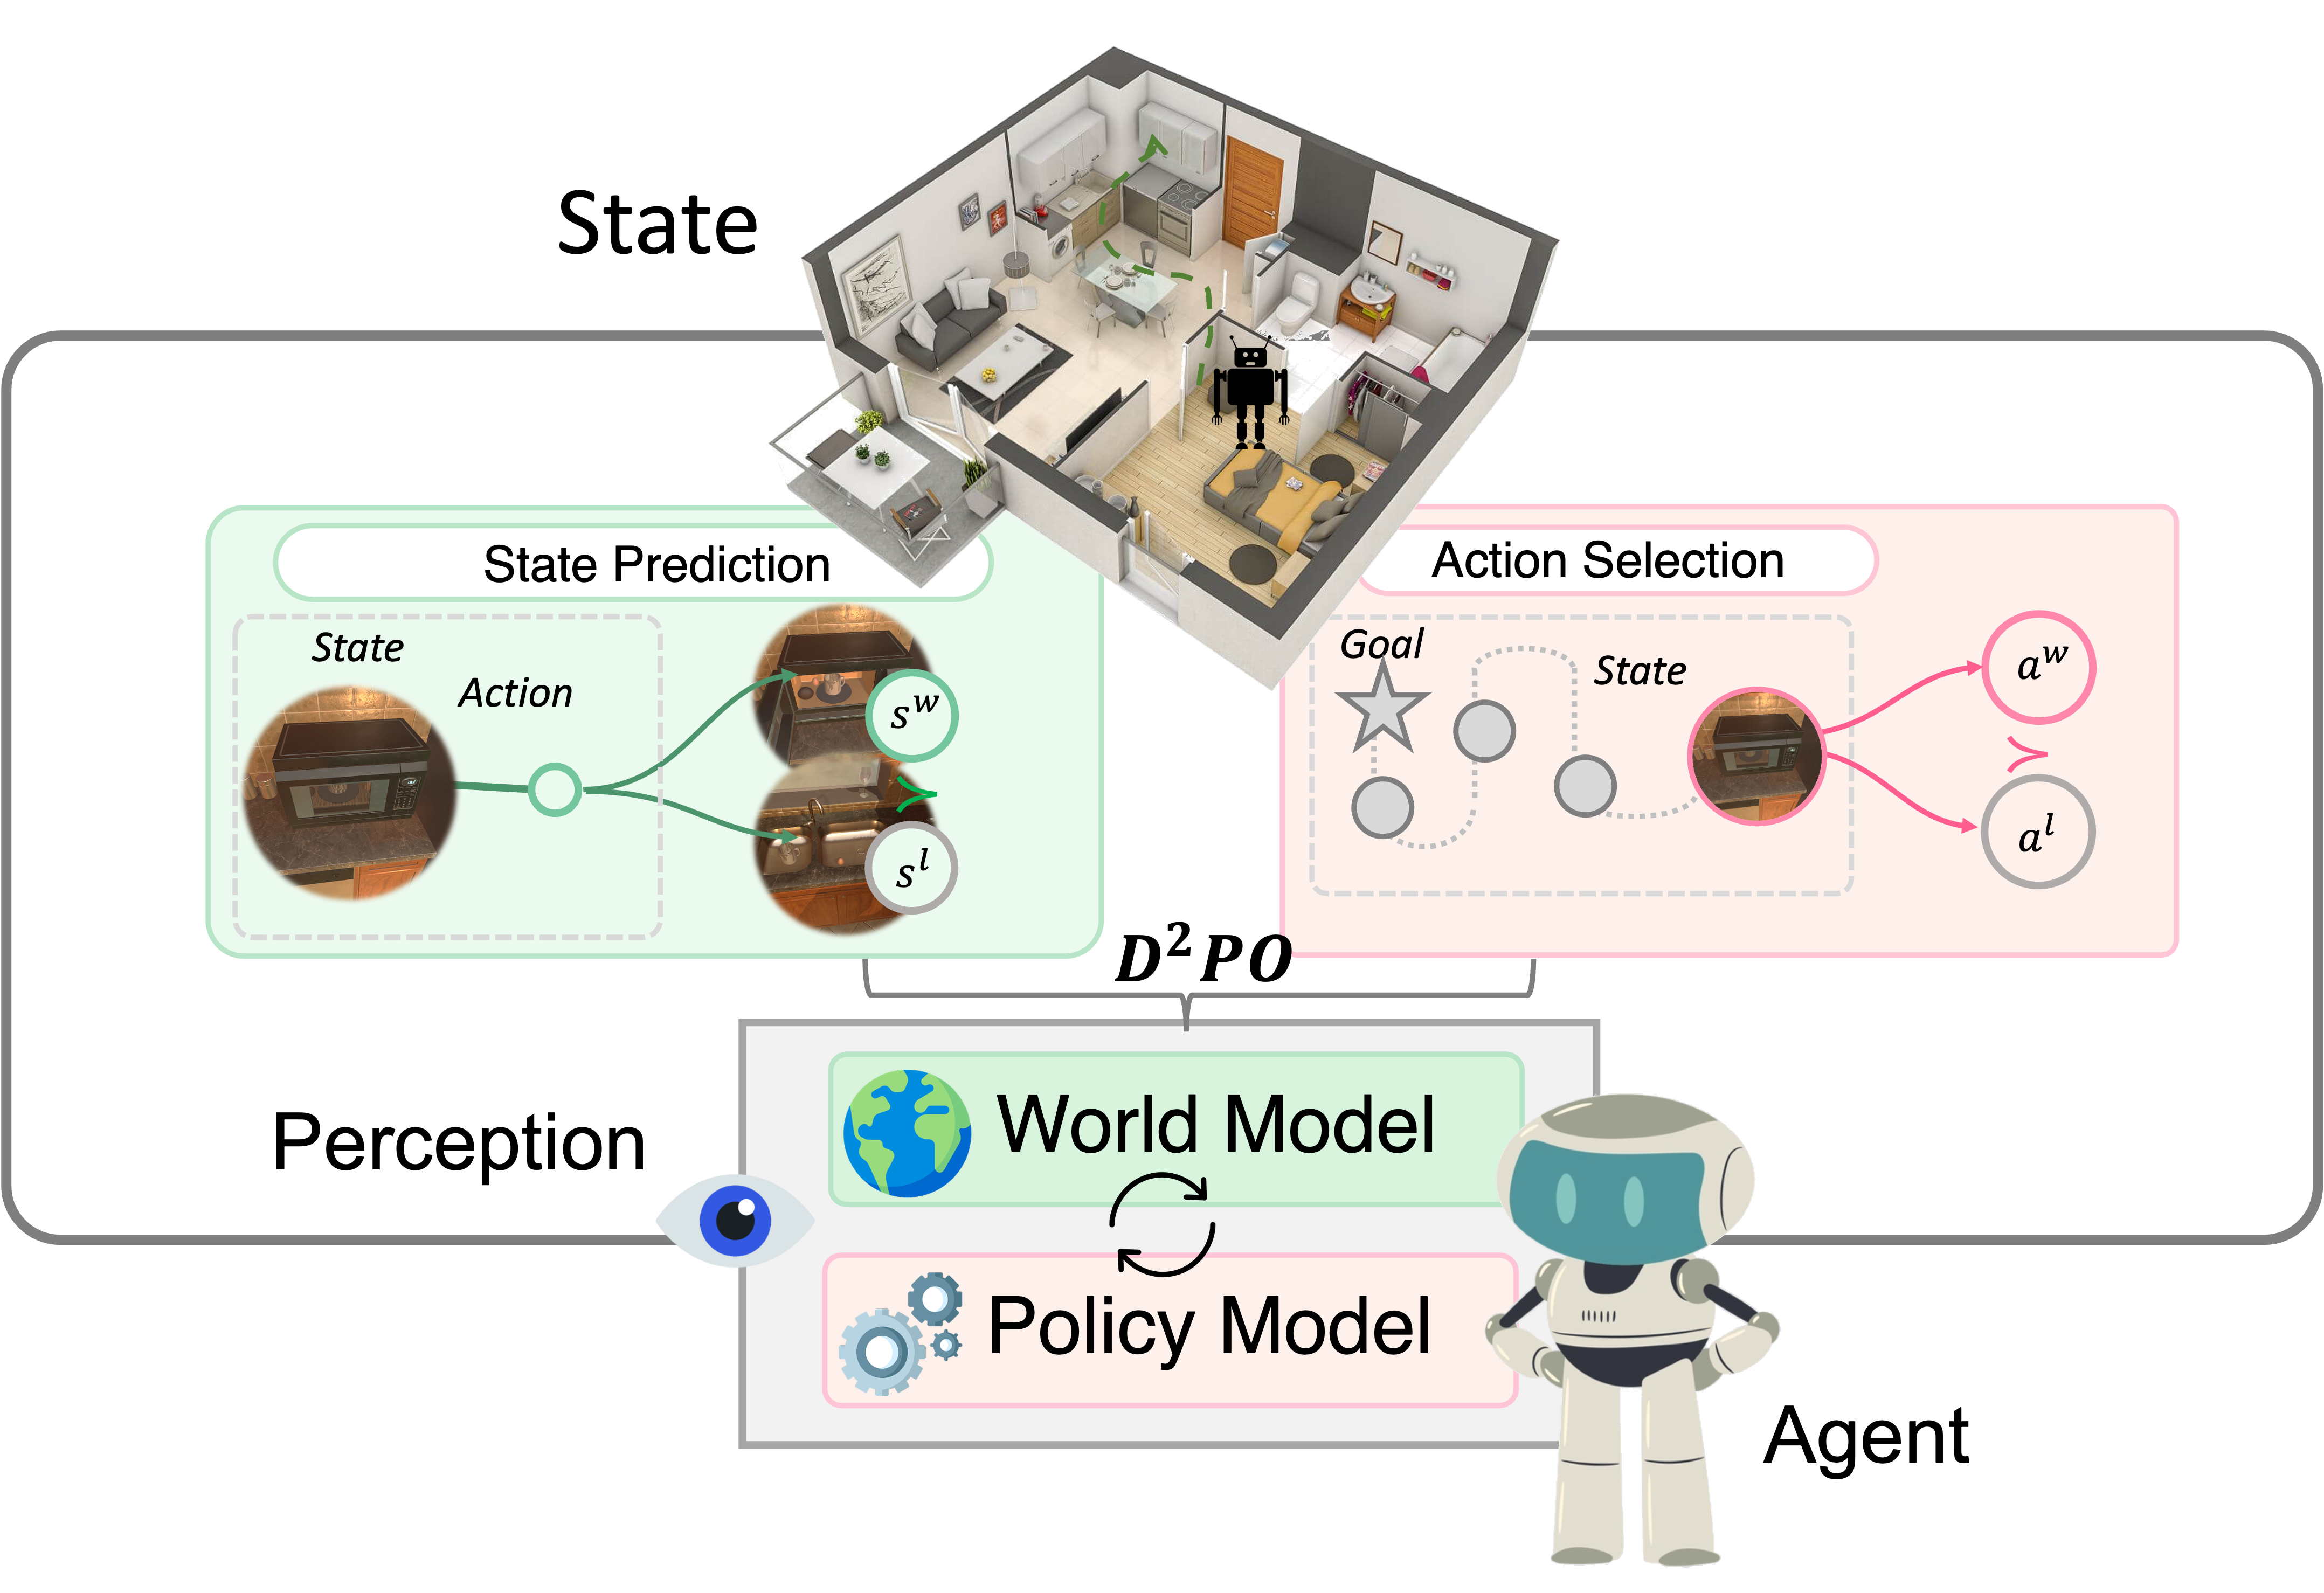
- Three papers were accepted to ACL 2025: D²PO for joint world modeling and embodied planning; weak-to-strong generalization through better supervision and question selection; and VisuoThink for visual-textual reasoning with tree search!
- We launched MOSI Intelligence, a startup focused on contextual intelligence and AI systems that understand and interact with their surroundings.
- We released SpeechGPT 2.0-preview, an end-to-end Chinese spoken dialogue model for low-latency, real-time interaction, with natural interruptions and controllable voice styles!
- Turn Waste into Worth was accepted to EMNLP 2024! Our Rectify-Router recovers dropped tokens and reduces padding waste in mixture-of-experts models.
- Balanced Data Sampling was accepted to Findings of ACL 2024! ClusterClip balances common and rare training examples while limiting repetition to reduce overfitting.
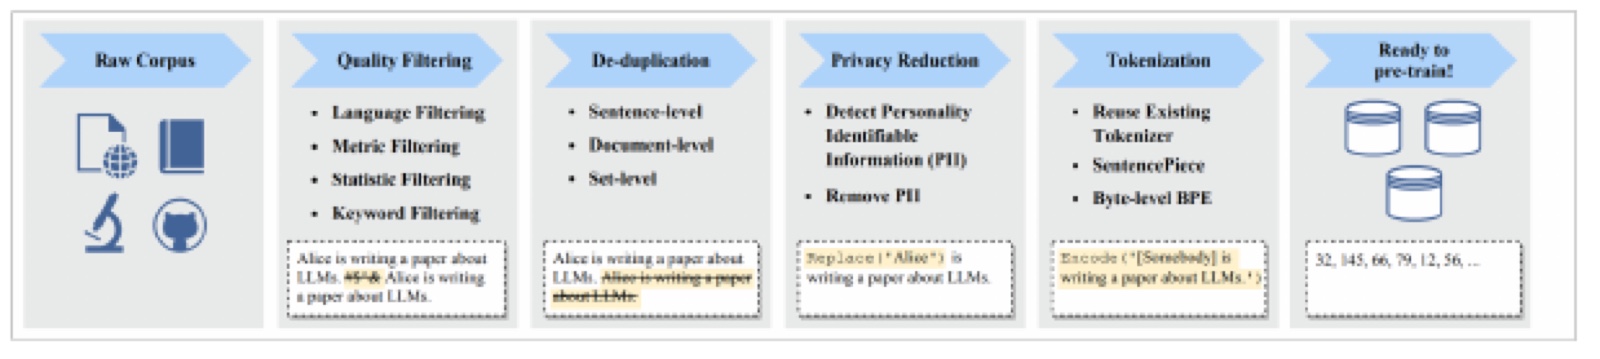
- We released WanJuan-CC, an English web corpus curated through deduplication, safety filtering and quality screening, with 100B tokens available for language-model pre-training!
- We shared the InternLM-Math technical report, unifying mathematical problem solving, solution verification, code-assisted reasoning and Lean theorem proving in one model family!
- We released InternLM2, with improved reasoning, coding and long-context capabilities! I was responsible for exploring its post-pretraining (mid-training) stage.
- We updated InternLM-7B-Chat and InternLM-20B-Chat, refining their instruction tuning for higher-quality responses and greater stylistic diversity!
- We released InternLM-20B, expanding the model family with a larger multilingual model trained on English, Chinese and code, alongside a chat version!
- We released InternLM-7B, an open 7B-parameter language model trained on trillions of tokens for general-purpose language understanding and generation!
- We released the first InternLM technical report, presenting a 104B-parameter multilingual model built through progressive pre-training and human-preference alignment!
- I joined Shanghai AI Laboratory to work on large language model pre-training and contribute to the InternLM project.
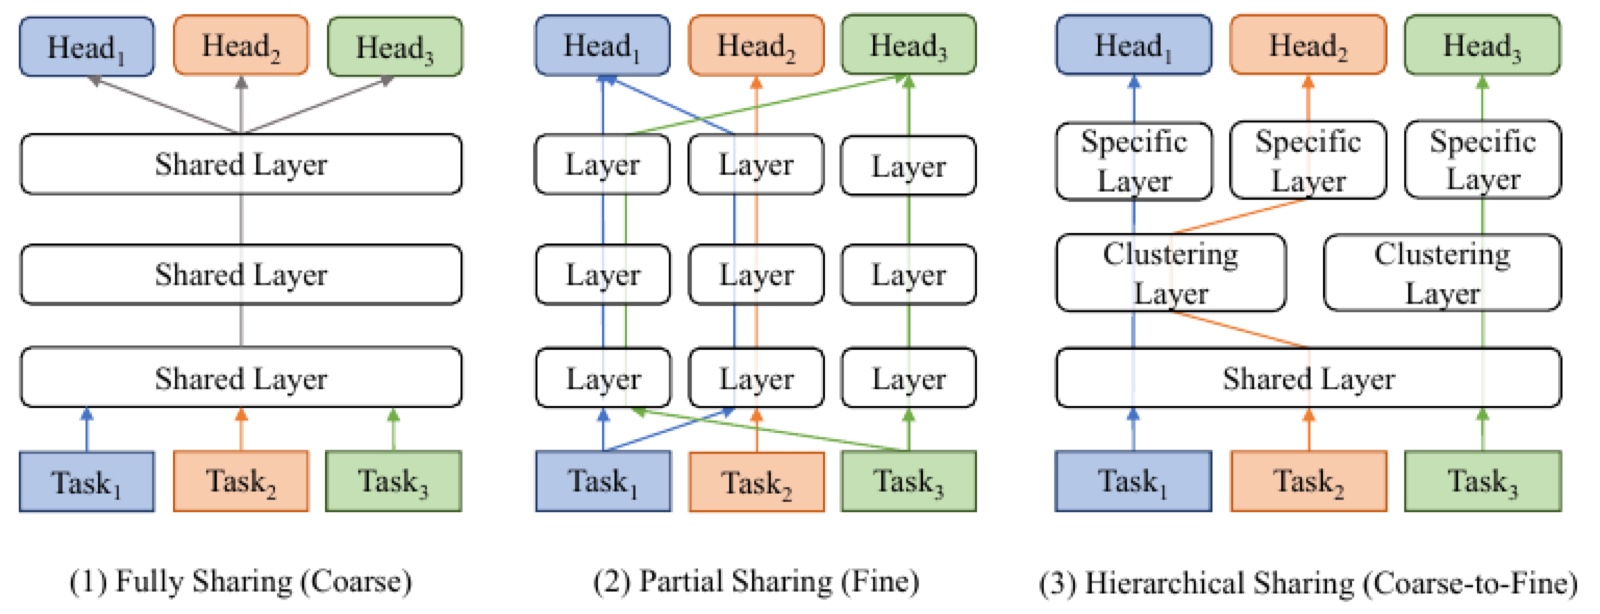
- Coarse-to-Fine was accepted to COLING 2022! We develop hierarchical multi-task learning that combines shared representations with task-group and task-specific layers for natural language understanding.
- I joined Huawei’s 2012 Laboratories as a research intern, working on sparse mixture-of-experts models and efficient expert routing.
- I joined FudanNLP under the supervision of Prof. Xipeng Qiu, beginning my research in natural language processing.
Selected publications
Selected peer-reviewed papers. * denotes equal contribution where indicated.
Full list of papers can be found at Google Scholar / Semantic Scholar / DBLP.

Technical reports & preprints
Selected technical reports and preprints.
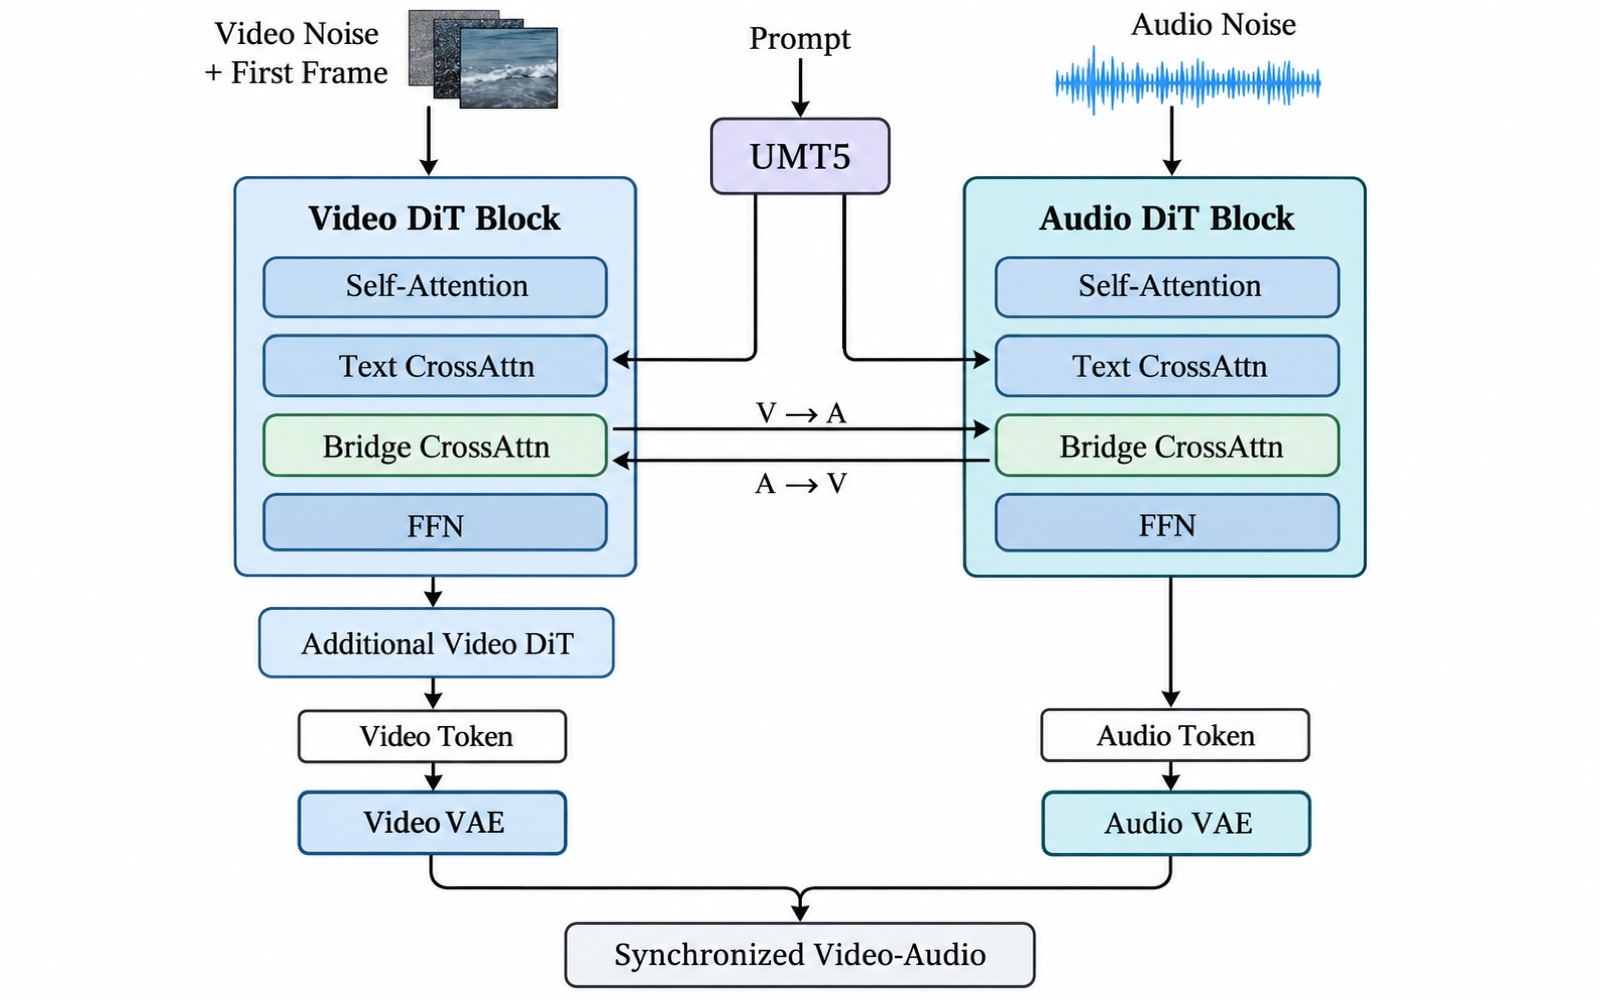
MOVA: Towards Scalable and Synchronized Video-Audio Generation
Honors & awards
-
NVVSpeech Challenge at ISCSLP 2026
Team mentor · 1st place in Track 1 and 2nd place in Track 2
-
US$10,000Prize
SmartGlasses Challenge 2026
Team mentor · 1st place in both tracks
-
US$10,000Prize
2nd MLC-SLM Challenge
Team mentor · 1st place in both tasks
-
Outstanding Graduate, Fudan University
-
11th National College Student Information Security Competition
Second Prize
-
¥10,000Prize
Wending Cup Cybersecurity Competition
First Prize
-
¥10,000Prize
Enterprise Intranet Security Cyber Range Competition
Second Prize
Academic service
Program Committee: AAAI (2027)
Reviewer:
- ARR (2024, 2025, 2026)
- NeurIPS (2024, 2025, 2026)
- ICLR (2024, 2025, 2026, 2027)
- ICML (2025, 2026)
- AISTATS (2025, 2026, 2027)
- ECCV (2026)
- TMLR
Find me online
LLM pre-training & multimodal integration
Embodied intelligence · Human–AI interaction
HuaFa Road St.699 No.3
shanghai